Cloud TPUs
Overview
Cloud TPUs are Google-built Tensor Processing Units, which are custom ASICs designed to accelerate machine learning workloads.
- Built for matrix-heavy AI and ML computation.
- Optimized for large-scale training and inference.
- Integrated into Google Cloud AI infrastructure.
Cloud TPUs work best when workloads are large, parallel, and tensor-dominant.
- Train large deep learning models, including LLMs.
- Accelerate embedding-heavy models using SparseCores.
- Run scientific and healthcare AI workloads such as protein folding and drug discovery.
It is a strong fit when your workload needs higher throughput than general-purpose compute can deliver.
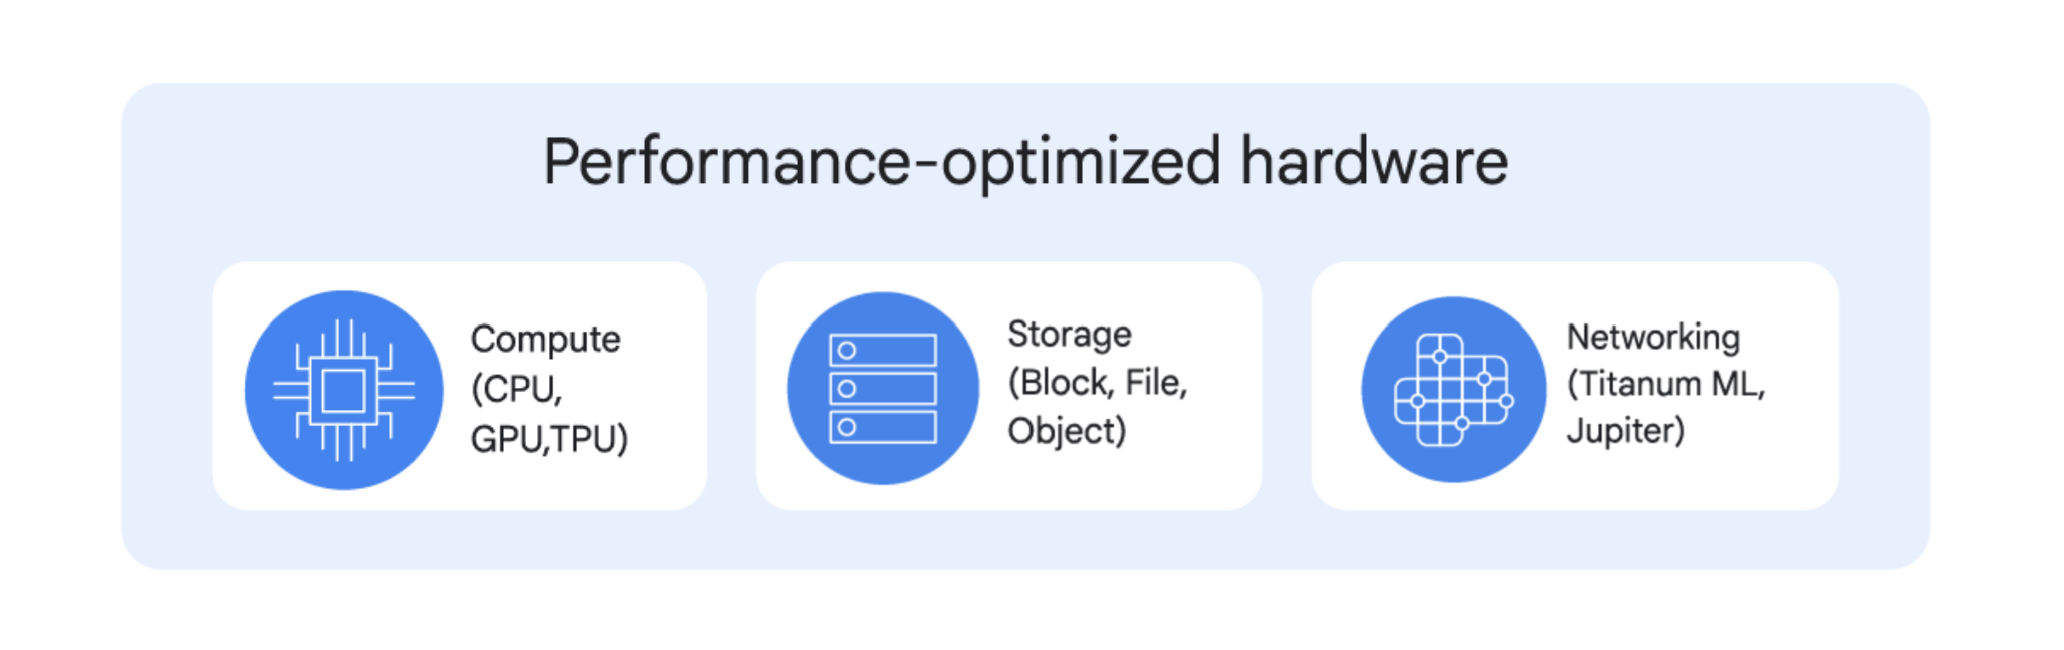
If your bottleneck is large-scale linear algebra, Cloud TPUs are often the right accelerator class.
How Cloud TPUs Work
Code that runs on TPUs is compiled by XLA (Accelerator Linear Algebra).
- XLA takes the computation graph from frameworks such as JAX or PyTorch.
- It compiles tensor operations into TPU machine code.
- The TPU VM image includes XLA and runtime dependencies.
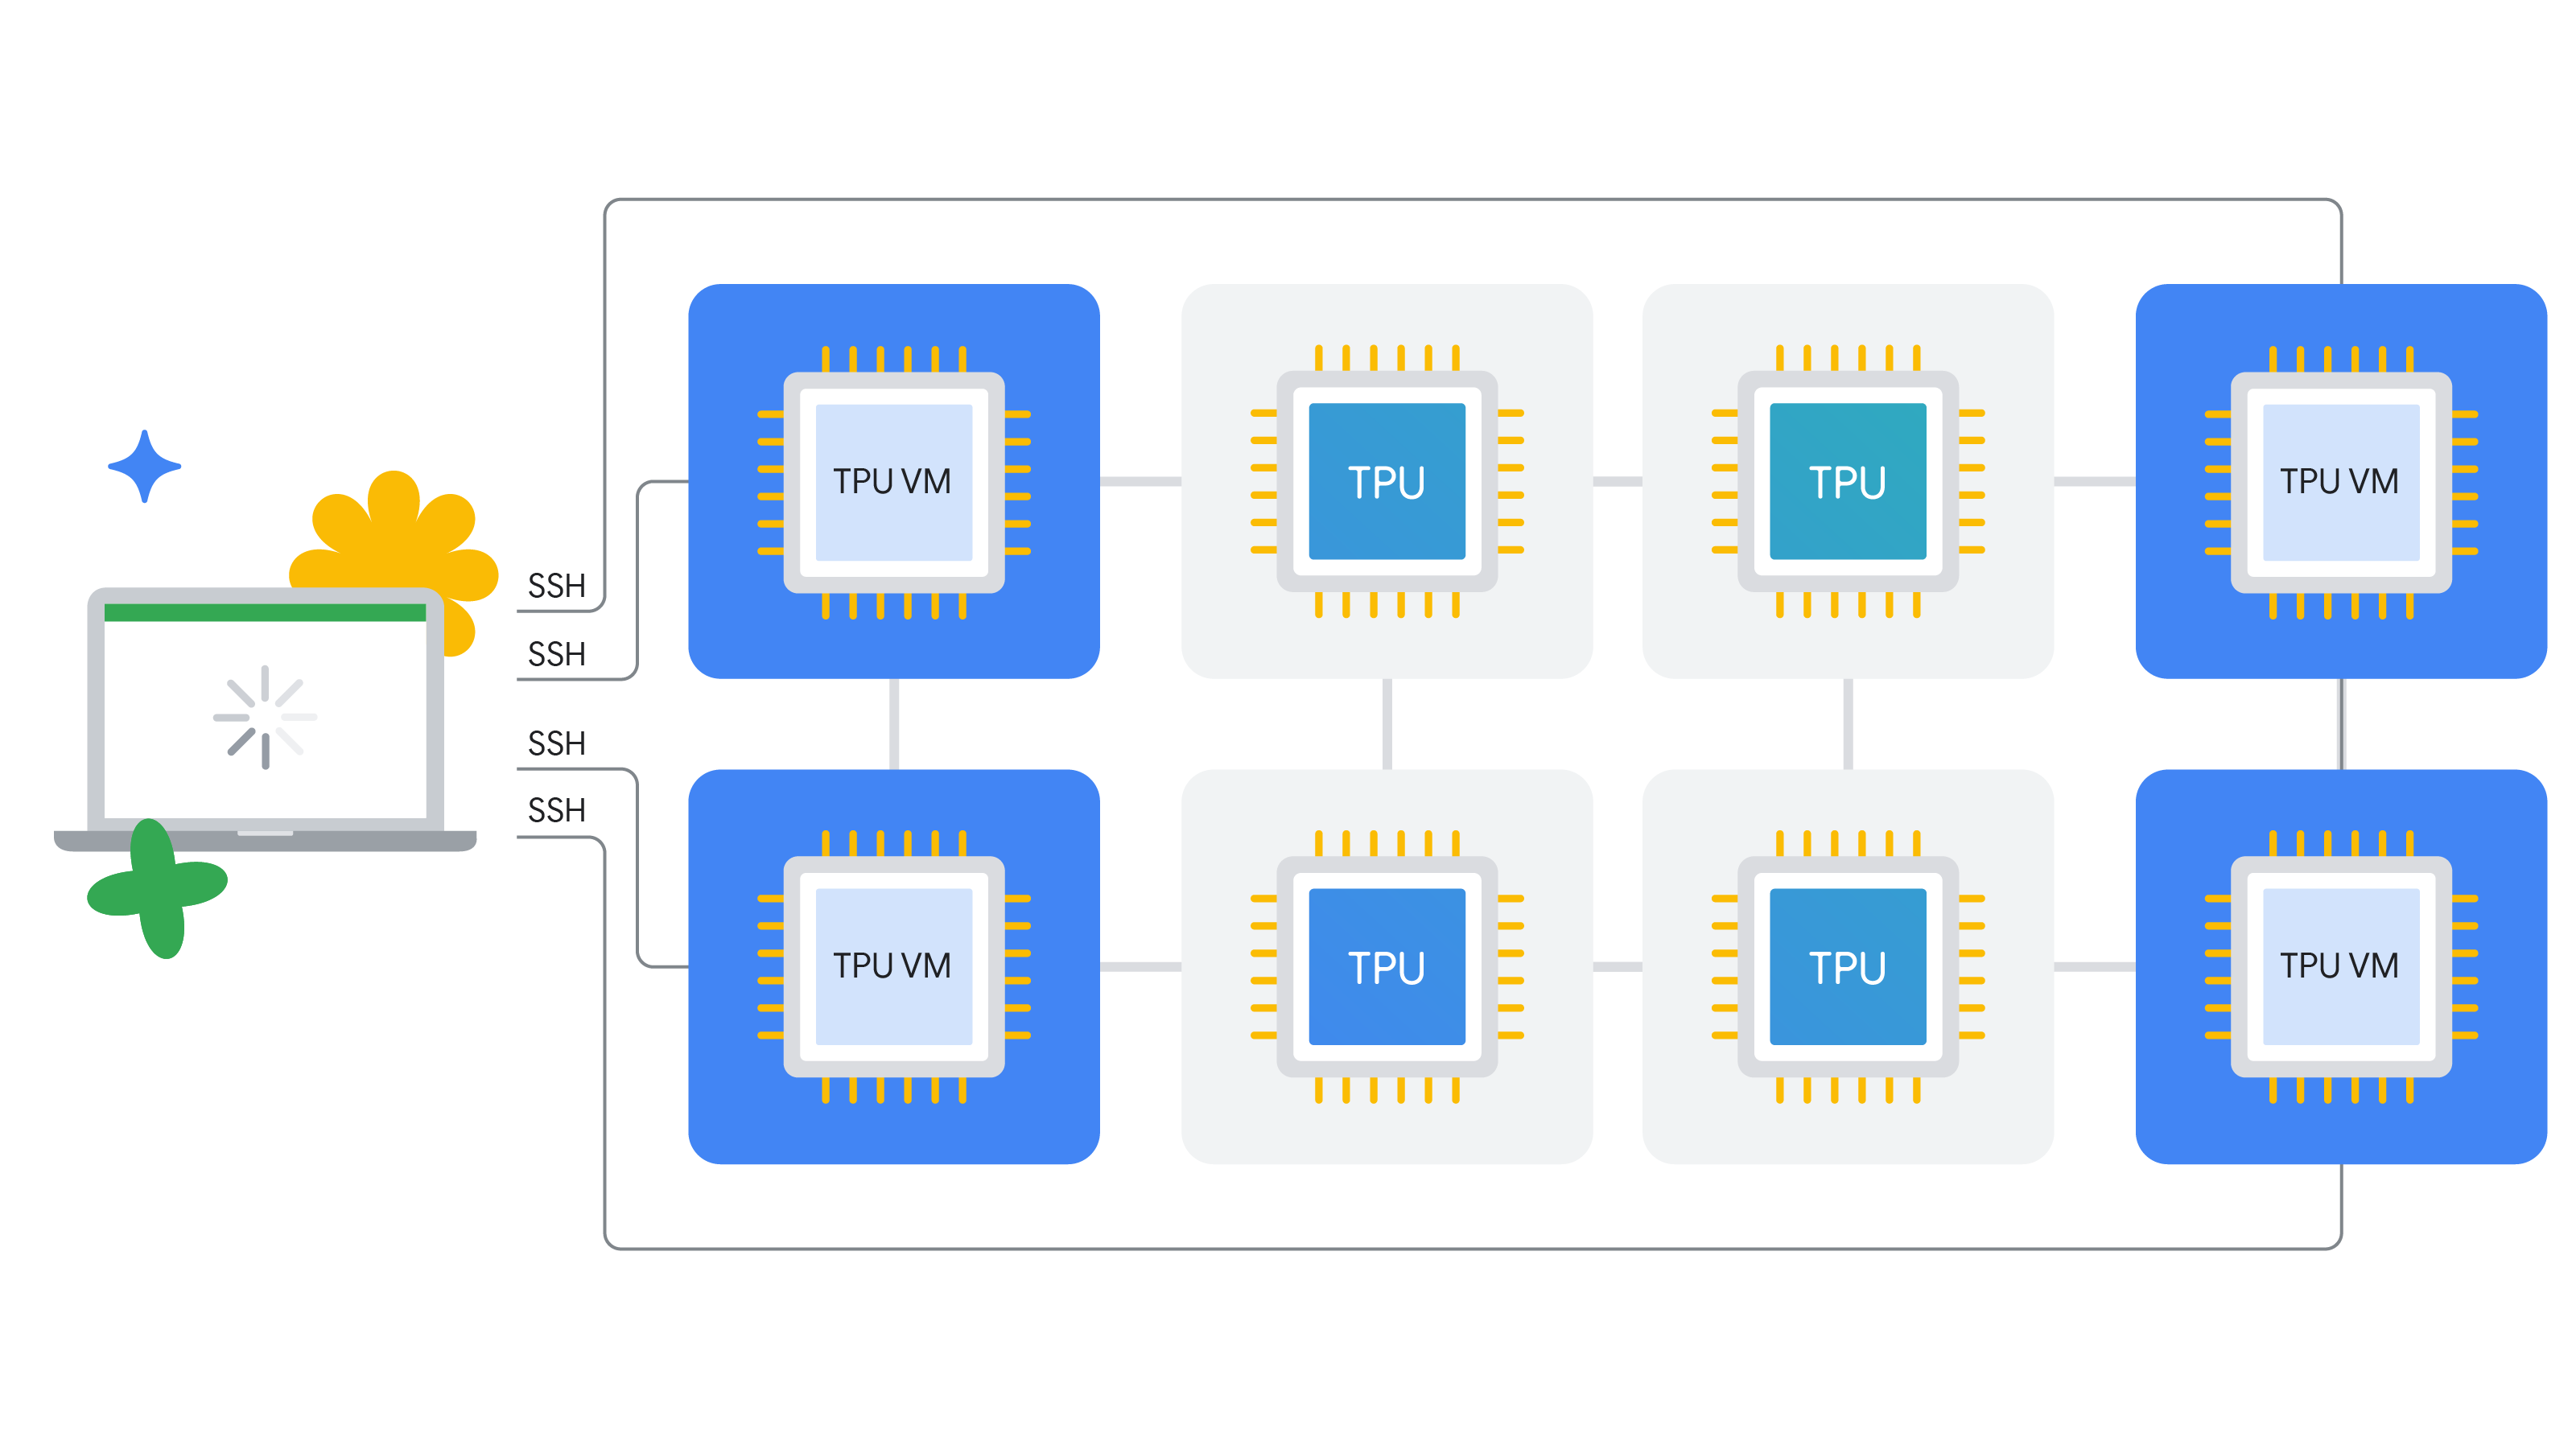
The TPU executes accelerated tensor math, while the host VM runs the rest of your application logic.
Benefits of Cloud TPU
Cloud TPUs provide practical advantages across training, fine-tuning, and inference.
- Cost-efficient scaling for high-demand workloads.
- Framework flexibility through XLA-based acceleration.
- Deep integration with GKE and Agent Platform.
- High-performance interconnect and scheduling options.
TPU v4 and later generations also benefit from reconfigurable optical circuit switching, which improves utilization, scalability, and resilience for very large jobs.
TPU System Architecture
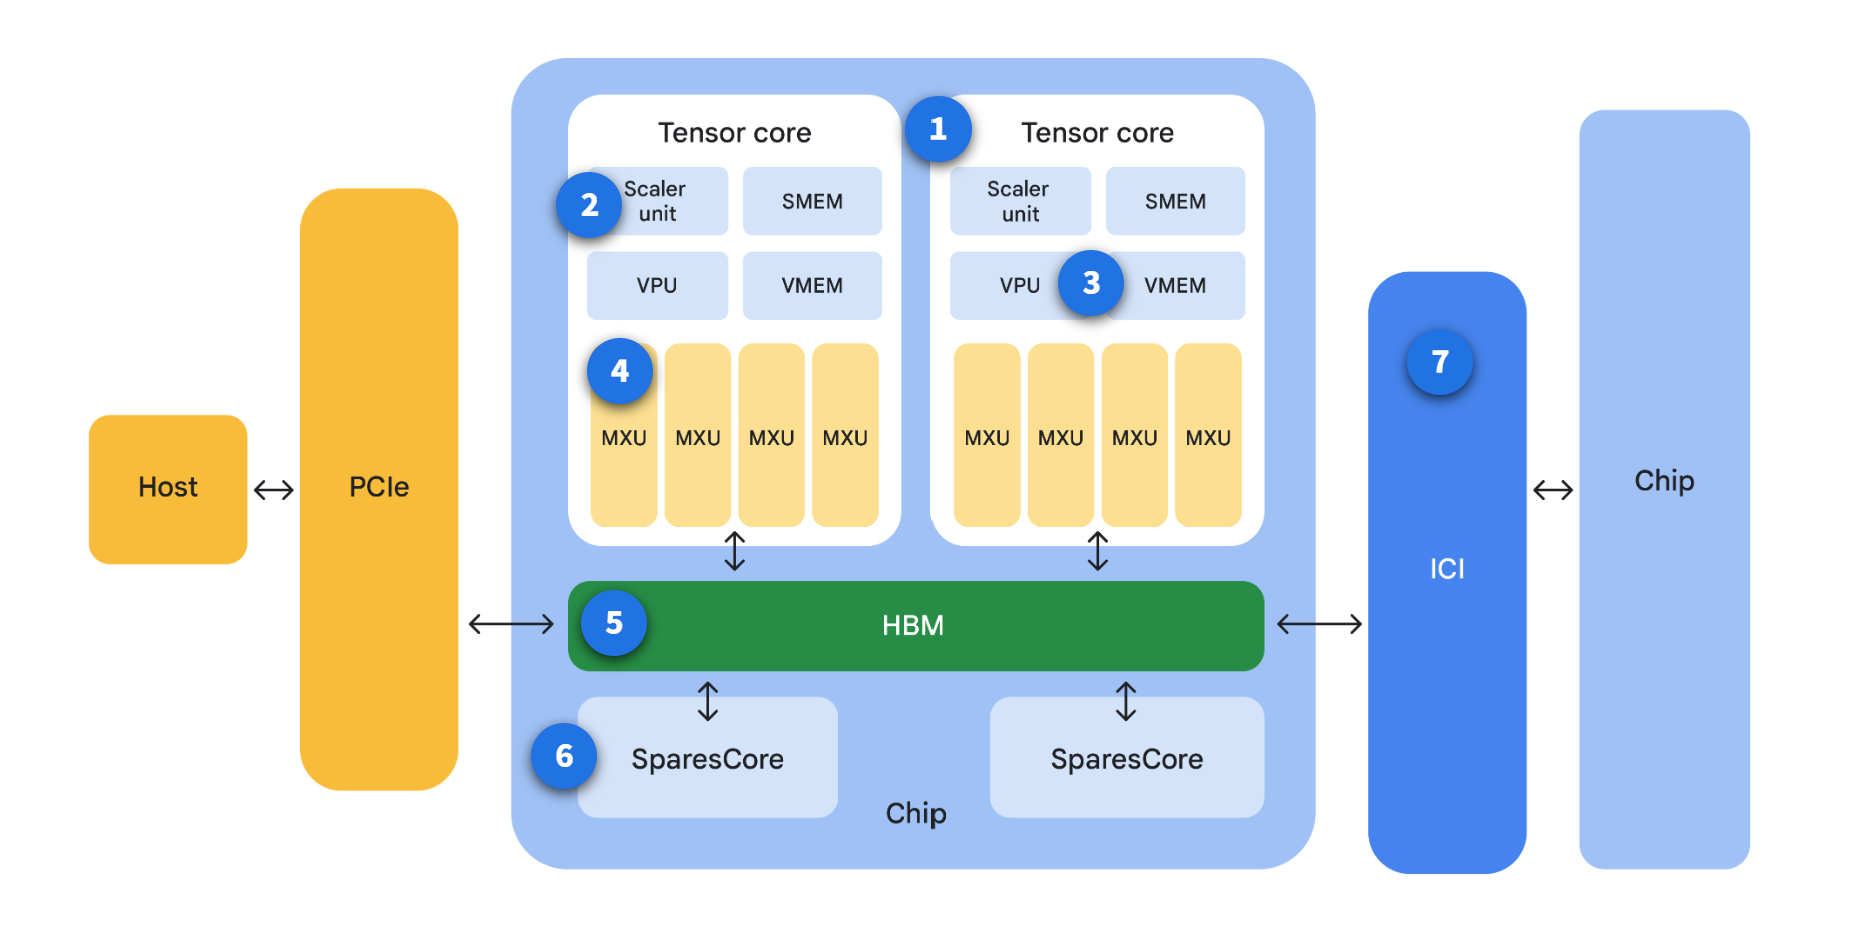
At the hardware level, each Cloud TPU chip combines specialized processing units for tensor operations.
For more information, please see TPU System Architecture.
TPU Deployment Architecture
Cloud TPU workloads can be run through direct VM management or managed platforms.
For more information, please see TPU Deployment Architecture.